The setup
The 3 offline objectives (DPO, IPO, AOT) differ on 2 axes: the shape of the loss on the reference-corrected margin \(\Delta_\theta\), and the granularity at which margins are compared.
- DPO is per-pair and unbounded. It pushes \(\Delta_\theta \to \infty\) for every pair, so it fits individual labels hardest (including the wrong ones).
- IPO is per-pair and bounded. It regresses \(\Delta_\theta\) to \(1/2\beta\), so once a pair hits the target the gradient vanishes.
- AOT is distributional. It sorts chosen and rejected rewards within the batch and compares them at matched quantiles. This is robust to mislabeled pairs, but it stops being effective once the chosen distribution is determined.
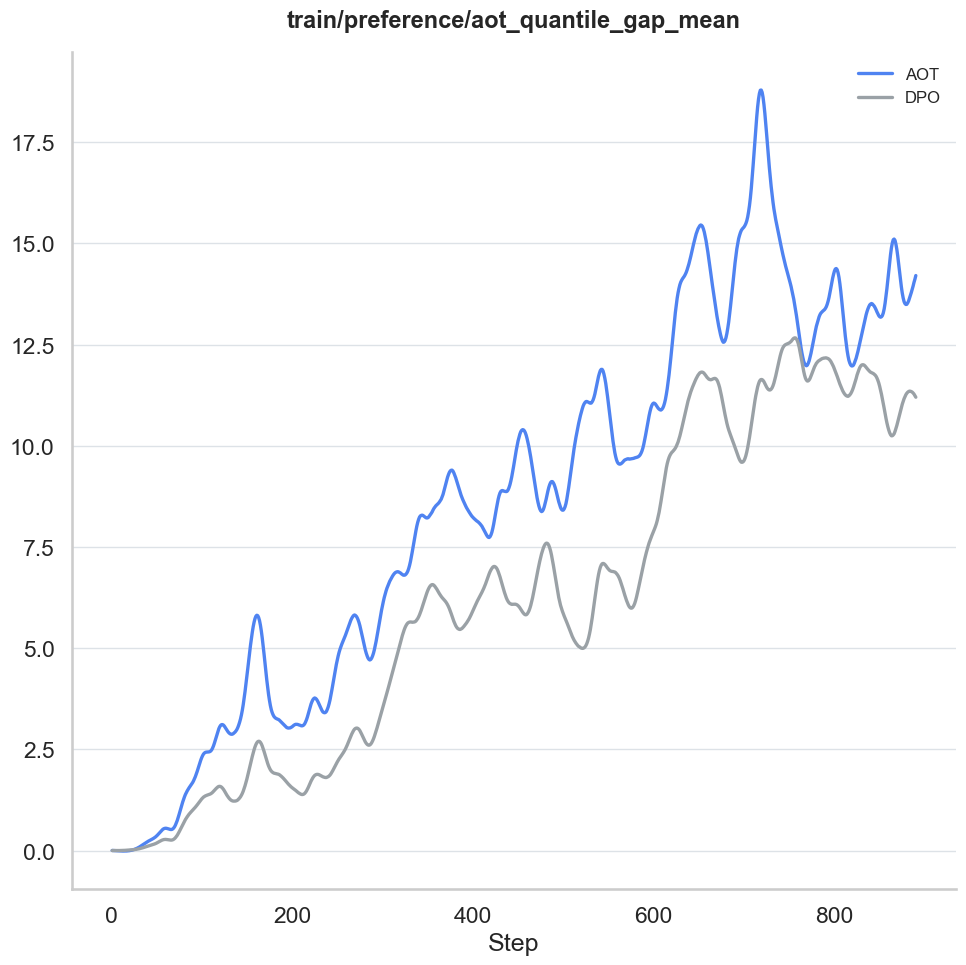
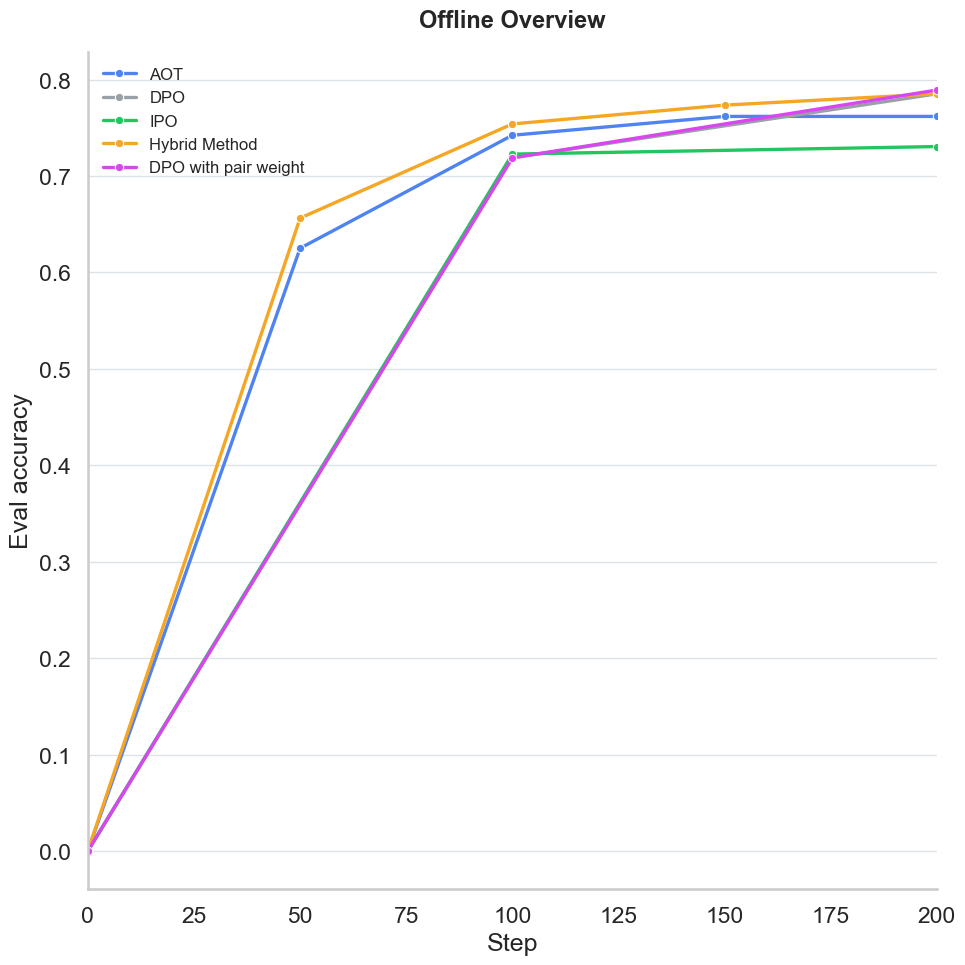
This suggests a hybrid schedule. AOT distribution-level signal is most useful early, while the policy is still far off. DPO per-pair signal is useful later, once only a few hard pairs remain. So we can anneal from one to the other:
\[\mathcal{L} = (1-\alpha_t)\,\mathcal{L}_{\text{AOT}} + \alpha_t\,\mathcal{L}_{\text{DPO}}, \qquad \alpha_t: 0 \to 1.\]We combined it with 2 other changes. Confidence-weighted DPO scales each pair’s loss by a weight in \([0.7, 1.3]\) derived from the dataset’s judge confidence. Reward-model reranking picks the highest-scoring response from a pool of policies.
Results
| Method | Win rate (mean ± std, 3 seeds) |
|---|---|
| DPO | 0.763 ± 0.044 |
| AOT | 0.754 ± 0.005 |
| GRPO | 0.732 ± 0.061 |
| GSPO | 0.723 ± 0.017 |
| IPO | 0.672 ± 0.029 |
| DrGRPO | 0.610 ± 0.005 |
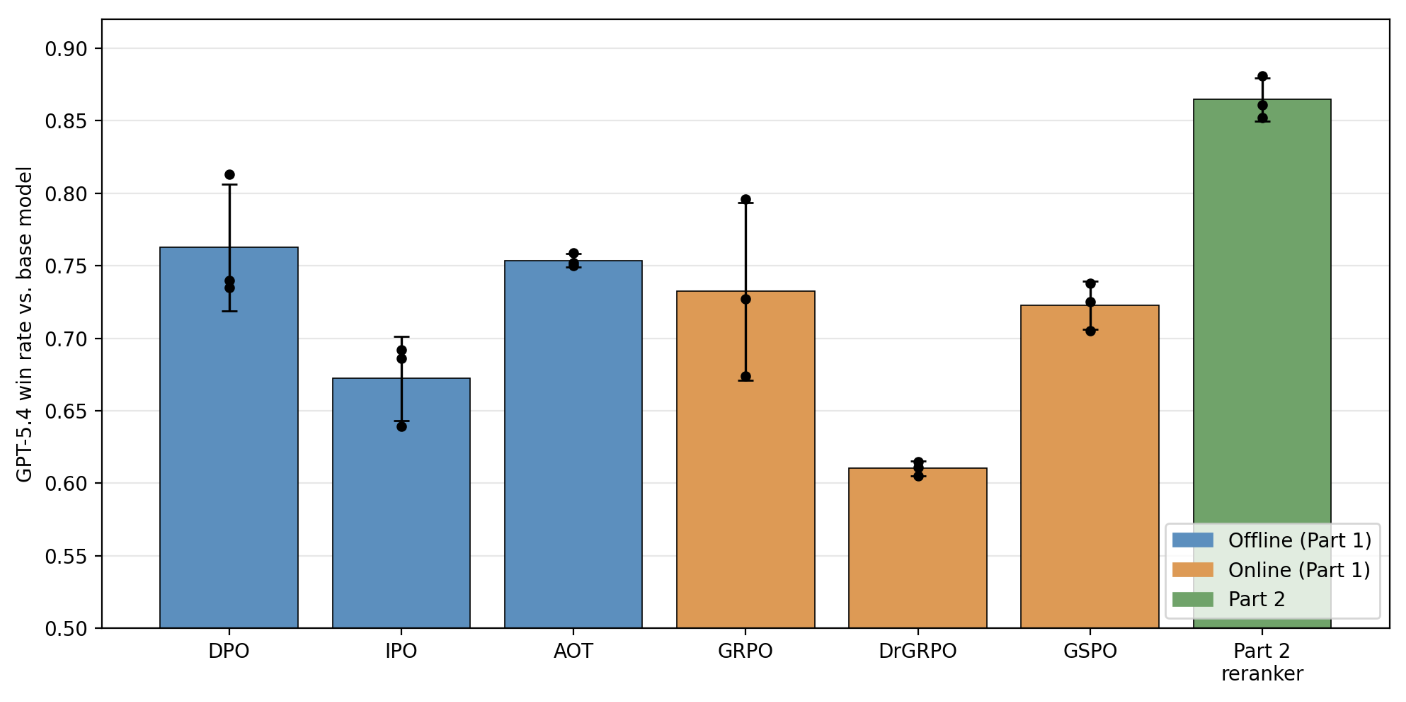
| Hybrid + reranking | 0.865 ± 0.015 |
Every seed of the final pipeline beats every baseline’s mean. Note that DPO and AOT have the same mean, but AOT’s seed variance is almost 10× smaller. GRPO produced both the best single baseline run and one of the worst, the high variance is probably due to our 25-step online budget.